Skip to content

Wikimedia Europe

Visual Portfolio, Posts & Image Gallery for WordPress

NASA Goddard Space Flight Center from Greenbelt, MD, USA, Public domain, via Wikimedia Commons

Michael S Adler, CC BY-SA 4.0, via Wikimedia Commons

Markus Trienke, CC BY-SA 2.0, via Wikimedia Commons

Charles J. Sharp, CC BY-SA 4.0, via Wikimedia Commons

JohnDarrochNZ, CC BY-SA 4.0, via Wikimedia Commons

Benh LIEU SONG (Flickr), CC BY-SA 4.0, via Wikimedia Commons

Stefan Krause, Germany, FAL, via Wikimedia Commons

We are Wikimedians working on EU policy to foster
free knowledge, access to information and freedom of expression.

{{CITATION NEEDED}} WHAT THE WIKIMEDIA ATTRIBUTION FRAMEWORK ASKS FROM AI
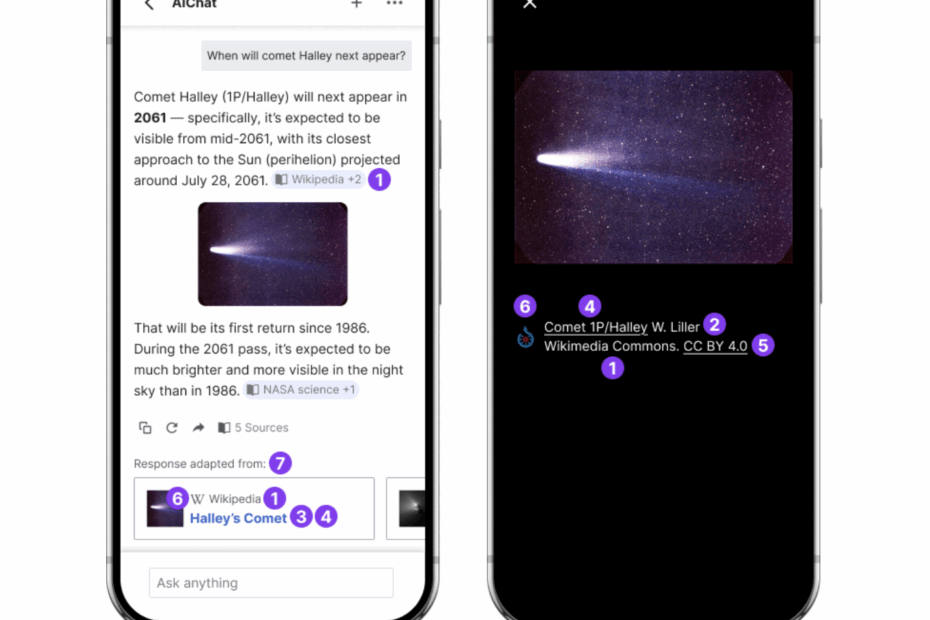
Ask an AI assistant a factual question and the answer may well draw on Wikipedia, yet you don’t always see it. This is the case with many sources on the internet. Publishers, libraries and broadcasters face similar questions. As the EU debates how AI, transparency, author’s rights and sustainability fit together, a basic question deserves its share of attention: When AI systems, search engines and apps reuse content, can people see where it came from? Is it clear which part of the answer is a citation and which is edited or added? Can we guarantee that the source is not misrepresented?
This post explains the Wikimedia Attribution Framework, a practical, voluntary answer from the Wikimedia Foundation, and what Wikimedia would like AI companies to do with it.
Read More »{{CITATION NEEDED}} WHAT THE WIKIMEDIA ATTRIBUTION FRAMEWORK ASKS FROM AI

Thirty-one Wikimedians, eighteen countries, two days: what we did at the 11th Big Fat Brussels Meeting

Every autumn, Wikimedia Europe brings together a group of Wikimedians who care about policy — volunteer advocates, staff, and people from like-minded organisations. Last week we held the eleventh edition of what we have always called, half-jokingly, the Big Fat Brussels Meeting. Thirty-one people from eighteen countries. Two days. Here’s a quick recap.

Read More »Thirty-one Wikimedians, eighteen countries, two days: what we did at the 11th Big Fat Brussels Meeting

Deepfake laws across Europe: what do they look like and what do they mean for Wikipedia

Deepfakes are understood as realistic images, audio and video of real people that are generated or manipulated with AI. They can be used for parody, satire or to express valid social criticism. But they can be harmful in the cases of fraud, economic damages, disinformation and non-consensual intimate imagery.

Lawmakers in several EU countries (Belgium, Denmark and Cyprus) are trying to answer with new rights over a person’s likeness and voice, usually placed in copyright or neighbouring-rights law.

For the Wikimedia projects, which host and reuse media under free licences and also document public events and debates (including deepfake incidents themselves), the details of these laws matter. So let’s take a closer look!

Read More »Deepfake laws across Europe: what do they look like and what do they mean for Wikipedia

Turning Open Knowledge Into Public-Interest AI-Infrastructure: The Wikidata Embedding Project

As generative AI tools become the default way many people search for information, the question of where that information comes from matters more than ever. Wikimedia Deutschland’s Wikidata Embedding Project offers a concrete answer: it turns Wikidata’s vast, community-verified knowledge base into something small AI systems and humans can use to enable searches by meaning, not just by keyword. It demonstrates what public-interest AI infrastructure can and should look like. 

Read More »Turning Open Knowledge Into Public-Interest AI-Infrastructure: The Wikidata Embedding Project

Editorial: Europe should protect children online. It shouldn’t have to check everyone reading an encyclopedia

To buy a bottle of wine or a pack of cigarettes in Europe, you show an ID. That makes sense: these products carry real, well-documented risks to minors, and a quick glance at a card is enough to stop the sale. Now imagine that same threshold applied to anyone opening a browser to look up Kandinsky, or the article about Ithaca. Exactly this is the direction many lawmakers are heading to.  

Read More »Editorial: Europe should protect children online. It shouldn’t have to check everyone reading an encyclopedia

How the Wikipedia model can help improve platform regulation: Recommendations for future policy-making from the DEM-DEBATE Project

The DEM-Debate project spent almost two years investigating how Wikipedia addressed disinformation during the 2024 European elections through legal and computational analyses. This final report, produced by researchers from the University of Amsterdam and Eurecat – Centre Tecnològic de Catalunya, delivers two sets of recommendations: one specifically targeting the upcoming revision of the Digital Services Act (DSA), and one drawing on Wikipedia’s governance model as a blueprint for the broader online information ecosystem. These recommendations are aimed to inform future regulation on platform regulation to strengthen the resilience of the information ecosystem.

Read More »How the Wikipedia model can help improve platform regulation: Recommendations for future policy-making from the DEM-DEBATE Project

25 Years of Wikipedia

On 18 March, Wikimedia Europe and Wikimedia Belgium brought together a room full of people who care deeply about one of the internet’s quirkiest and perhaps most surprising achievements: 25 years of Wikipedia. Think about what that actually means. A non-commercial, volunteer-built encyclopedia in hundreds of languages, freely available to anyone with an internet connection. No paywalls. No shareholders. No algorithm deciding what you should read next. Around 260,000 volunteers curate 65 million entries, viewed more than 15 billion times every month. We don’t have nearly enough of that kind of thing. A room full of communities The evening had the feel of a reunion — familiar faces from across the European digital policy and Wikimedia communities. A mini-exhibition taking guests through the history of Wikipedia. A Wikicheese station where volunteers photographed Belgian cheeses to improve culinary content on the internet. These things only happen when people have been genuinely building something together long enough that the work creates its own history. Annie Rauwerda Stand-up Wikipedian and Depths of Wikipedia creator Annie Rauwerda took the stage and did what she does best — making the audience laugh while quietly reminding everyone why Wikipedia and free knowledge is beautiful. Her show was a love letter to trivia, knowledge, facts and humans. You may watch an older version of her talk online. Here’s to the next 25. One accent was the conscious decision to celebrate being human. Wikipedia is a project of humans and dedicated to human knowledge. With everything that this entails – good and bad. In a world full of machine generated content, the Wikimedia movement wants to confirm its commitment to being community human of volunteers first and foremost. And since we are human, you will also bear with us that we will plug… Read More »25 Years of Wikipedia

THE DEM-Debate project came to an end: the final event

On February 24, the DEM-Debate partners – Wikimedia Europe, the University of Amsterdam and Eurecat – Centre Tecnològic de Catalunya – gathered at the European Parliament in Brussels for the final event of the DEM-Debate project. 

Read More »THE DEM-Debate project came to an end: the final event

The Architecture conflict vs. the architecture of collaboration

Open your social media feed. Within thirty seconds you will likely have seen something engineered to provoke you — a post calibrated by an algorithm to raise your cortisol, confirm your suspicions about the “other side”, or send you spiralling into an outrage loop that keeps you scrolling. This is not a bug. It is the business model. Platforms built on advertising revenue seem to have discovered, empirically, that anger and anxiety are among the most reliable engines of engagement. So their algorithms are optimised for both.

Now open Wikipedia. You land on an article. At the top, perhaps, a small notice: “This article’s neutrality is disputed.” Or: “This article needs additional citations.” Or nothing at all — just the text, the citations, the talk page quietly humming in the background where a numerous strangers are negotiating the phrasing of a single contested sentence. This, too, is not an accident. It is the result of deeply intentional architectural choices — choices that point in precisely the opposite direction from the attention-advertising economy.

Read More »The Architecture conflict vs. the architecture of collaboration